
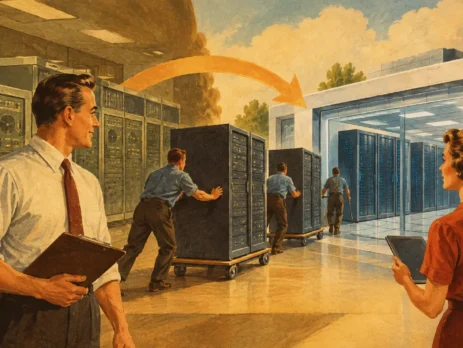
A Data Center Migration Example That Works
A failed cutover is rarely caused by the last command entered at 2:00 a.m. It usually begins weeks earlier with an incomplete interface inventory, an overlooked power requirement, a transceiver mismatch, or an application owner who was never assigned a validation task. This data center migration example shows how an enterprise can move critical network infrastructure to a new facility while controlling downtime, hardware risk, and recovery options.
The scenario is representative of a mid-sized organization consolidating two server rooms into a purpose-built data center. Its network supports internal business applications, internet edge connectivity, wireless controllers, storage traffic, voice services, and remote branches. The target facility has new racks, dual utility feeds, redundant UPS capacity, and upgraded core switching. The organization wants to modernize where it makes sense, but it cannot replace every device during the migration.
The Data Center Migration Example: Scope and Constraints
The existing environment includes two core switches operating as a virtual chassis, access switches, edge routers, firewalls, wireless controllers, and several older distribution switches that serve specialized equipment. Some applications are virtualized, while several physical servers remain connected through 1 GbE copper and fiber uplinks. The new data center is 18 miles away, so a simple cable-by-cable relocation is not possible.
The migration objective is to move production services in one weekend, with a maximum four-hour outage for user-facing applications. The technical team also has three constraints: the current WAN routers must remain active until branch connectivity is moved, older switches require specific power supplies and fan modules, and several multimode fiber runs use legacy SFP optics that are not compatible with every new switch platform.
This is where a migration plan becomes a procurement plan. Network design, device configuration, and parts availability have to align. A replacement power supply that arrives after the maintenance window is not a minor logistics issue if it prevents a core device from operating with redundancy.
Phase 1: Build an Inventory That Supports Decisions
The team begins with a physical and logical inventory. A spreadsheet alone is not enough unless it records the details needed to reconnect and validate each service. For every device, the record includes hostname, model, serial number, rack position, software version, power supply configuration, interface count, connected peer, optic type, VLAN or VRF assignment, and business service dependency.
The team discovers that the original documentation lists a 10 GbE uplink as a generic fiber connection. On inspection, it is a short-reach multimode SFP+ module running over OM3 fiber. The new core platform has compatible 10 GbE ports, but the target rack layout requires a longer fiber patch path. The team changes the patching design rather than assuming the existing optic will support the distance and cable type.
They also identify a single point of failure in an older router. It has only one available power supply and is needed to maintain a carrier handoff during the transition. Instead of accepting that risk, procurement secures a tested compatible spare power supply and the correct rack hardware before the migration window. Exact model and revision matching matters, particularly in mixed Cisco, Huawei, and legacy environments where physical fit does not guarantee operational compatibility.
Classify equipment by migration method
Each device is assigned one of three methods. Equipment can be moved as-is, replaced in the target site, or kept temporarily in the old site while services are extended across a transit connection.
Moving equipment as-is is appropriate for stable appliances with known configurations and supported power requirements. Replacing equipment is appropriate when the current hardware is end-of-life, lacks port density, or would introduce an avoidable outage risk. Keeping equipment temporarily in place is useful when a carrier circuit, specialized interface, or application dependency cannot be transferred during the main cutover.
The choice depends on operational exposure. Reusing a functioning switch may reduce cost and simplify configuration, but it increases the need for spare fans, power supplies, optics, and console access. Replacing it may improve capacity and supportability, but it creates a parallel build that must be tested before production traffic moves.
Phase 2: Design the Target Network Before Moving Hardware
At the new site, the team installs core switches, management switches, edge routers, and firewalls in their final rack locations. They label power feeds A and B, validate grounding, and confirm that each dual-power device is connected to separate PDUs. This is verified physically, not inferred from rack diagrams.
The target core is configured in advance with VLANs, routing protocols, access-control policies, network time settings, logging targets, and management access. Configurations are reviewed against the production baseline, then adjusted for the new addressing and uplink design. The team preserves a copy of every original running configuration and startup configuration in a controlled repository.
A temporary Layer 2 and Layer 3 transit path connects the old and new locations. Its purpose is not to carry all production traffic indefinitely. It gives the team a controlled bridge for staged migration, remote testing, and rollback. The transit capacity is calculated against expected replication, management, and temporary application flows. Under-sizing this link can make a technically correct plan fail under production load.
Phase 3: Test the Components That Commonly Cause Delays
A pre-cutover test should look beyond ping responses. The team connects representative servers to the target network and tests DNS resolution, authentication, firewall policy enforcement, storage reachability, monitoring, backup traffic, and application-specific ports. They confirm that interfaces negotiate at the expected speed and that optic diagnostics report acceptable transmit and receive levels.
This is also the time to test replacement hardware. Spare switches, router cards, SFP and SFP+ modules, stacking cables, power supplies, and flash storage should be powered on and recognized by the intended platform. A part number may appear correct in a bill of materials but still require a particular software release or hardware revision.
The team maintains a migration kit at each site. It includes labeled console cables, USB-to-serial adapters, known-good transceivers, fiber and copper patch leads, rack screws, cable managers, spare PSUs, and a laptop with approved configuration files. These are small items, but they determine whether an engineer can resolve a fault immediately or wait for an avoidable delivery.
Phase 4: Execute the Cutover in Controlled Waves
The weekend begins with a formal change freeze and a go/no-go review. The project lead confirms circuit status, staffing, backups, application owner availability, spare hardware, and the rollback threshold. Every task has an owner and a planned completion time.
The first wave moves noncritical services and validates the transit path. The second wave moves internal applications with clear test procedures. The final wave shifts internet edge routing, firewall policies, and branch connectivity. Routing changes are introduced in a sequence that avoids asymmetric paths through stateful firewalls.
For each wave, engineers verify device health, interface status, routing adjacencies, CPU and memory utilization, and log events. Application owners then validate actual business transactions, not only port connectivity. A finance system login, a warehouse scan, or a voice call provides more useful evidence than an ICMP reply.
The rollback plan is deliberately simple. If a critical validation step fails and the issue cannot be isolated within the defined recovery window, traffic returns to the old site through the documented routing reversal. The team does not attempt to troubleshoot indefinitely while the outage grows. A tested rollback is a control, not an admission of failure.
Phase 5: Stabilize, Document, and Retire the Old Site
After cutover, the team monitors performance and errors through the next business cycle. They review interface counters for drops and CRC errors, inspect firewall logs for denied application flows, and compare WAN utilization with the pre-migration baseline. They also verify that monitoring, configuration backups, and alerting are reporting from the new management addresses.
Only after the stabilization period do they remove temporary transit links and decommission old equipment. Devices intended for reuse are wiped according to company policy, tested, labeled, and stored with their compatible accessories. Equipment held as a strategic spare should include the components most likely to fail or be difficult to source, rather than an arbitrary collection of retired hardware.
A successful migration is measured by more than whether racks changed location. It leaves the organization with accurate port maps, current configurations, known spare-part requirements, and a network that can be supported after the project team has moved on. Treat the hardware bill of materials as an operational document, and the next maintenance window will be far less dependent on luck.

I am an enthusiastic tech blogger with 15 years of experience in the technology field. I am passionate about sharing valuable insights and helping people who are interested in technology gain useful and practical information. I am originally from Mumbai, India.

Leave a Reply