
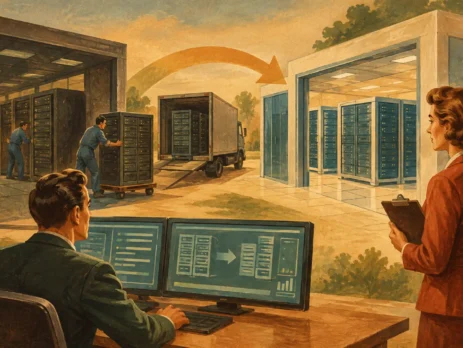
Data Center Migration Guide for Controlled Cutovers
A data center migration guide is only useful when it addresses the conditions that cause real cutovers to fail: undocumented dependencies, incompatible hardware, incomplete rollback plans, and equipment that does not arrive when required. For enterprise IT teams, a migration is not simply moving racks or virtual machines. It is a controlled change to power, network, compute, storage, security, and operational ownership.
The correct migration approach depends on the application estate, recovery objectives, target architecture, and available maintenance window. A small server-room consolidation can be completed over a weekend. A multi-site migration involving core routing, storage replication, and business-critical applications may require phased execution over several months. The planning discipline should be the same in both cases.
Define the Migration Scope Before Selecting a Method
Begin by stating exactly what is moving and what is changing. A relocation moves existing systems to a new facility with limited architectural change. A refresh replaces selected infrastructure during the move. A modernization may move workloads to new compute, network, or cloud platforms while retiring legacy systems.
These are different projects with different risks. Reusing existing switches, routers, power supplies, and optics may reduce capital expense, but it can extend the life of unsupported equipment or introduce compatibility constraints at the target site. Replacing hardware during the migration can simplify the final architecture, but it adds configuration, testing, procurement, and supply-chain dependencies.
Set measurable success criteria early. Define acceptable downtime by service, required recovery point objective, approved performance thresholds, security controls, and the point at which rollback is mandatory. A migration plan without clear acceptance criteria turns technical decisions into subjective decisions during the cutover window.
Build an Accurate Dependency Map
The configuration management database is a starting point, not proof of the current environment. Validate it against switch MAC address tables, routing tables, firewall rules, IP address management records, hypervisor inventories, storage mappings, monitoring data, and application-owner interviews.
Document dependencies in both directions. A database may appear to support one application but also provide authentication, reporting, batch processing, or licensing services for several others. A network segment may look inactive until a legacy controller, building system, or third-party device depends on it. Missing these relationships is a common reason migrations succeed at the infrastructure layer but fail at the business-service layer.
For each workload or service, record its owner, criticality, maintenance window, source and destination IP details, DNS dependencies, storage requirement, firewall flows, upstream and downstream systems, and validation test. This should produce a runbook that engineers can execute, not a high-level diagram that requires interpretation at 2:00 a.m.
Identify Network Dependencies at the Port Level
Network migration plans require more than an inventory of devices. Record switch models, supervisor or line cards, transceiver types, port speeds, media types, power requirements, software versions, routing protocols, VLANs, VRFs, access control lists, and management connections. Confirm whether existing SFP, SFP+, QSFP, power supply, stacking, and uplink modules are supported in the target hardware.
This detail matters when integrating legacy and current-generation equipment. A 10GbE uplink may require a specific optical module, direct-attach cable, breakout configuration, or software release. A replacement switch may have the required port count but lack the correct PoE budget, redundant power option, or compatible network operating system feature set.
Choose the Right Migration Pattern
There is no universal low-risk method. The most appropriate pattern follows the service design and business tolerance for interruption.
A physical relocation is practical for stable equipment with limited change requirements, although it demands careful de-racking, transport, re-racking, and post-move validation. Replication-based migration is often preferred for databases and virtualized workloads because data can be synchronized before cutover. Parallel operation provides the strongest operational safety for high-value services, but it requires duplicate capacity and more extensive testing.
A phased migration reduces blast radius by moving one application group, network zone, or business unit at a time. It also prolongs the period in which teams must operate two environments. A single cutover can reduce transition complexity, but only if dependencies are well understood and the rollback path is realistic.
Do not label a plan “zero downtime” unless every dependency has been designed for it. DNS changes, session persistence, database consistency, certificate distribution, carrier handoffs, and physical firewall changes can all introduce interruption even when compute workloads are replicated.
Design the Target Environment and Bill of Materials
The target data center should be designed from verified requirements, not from available inventory alone. Confirm rack layout, cabinet depth, rail kits, power feeds, plug types, UPS capacity, grounding, cooling, cross-connects, structured cabling, management network access, and physical security before equipment is shipped.
Create a bill of materials that separates mandatory migration components from recommended spares. Include exact part numbers and quantities for switches, routers, wireless controllers where applicable, power supplies, fans, transceivers, stacking cables, expansion modules, memory, flash, and licenses. For critical devices, plan spare units or at least rapid access to compatible replacement components.
Procurement timing deserves the same attention as technical design. Lead times for specific enterprise optics, legacy modules, and vendor-compatible replacement hardware can affect the entire cutover sequence. Teams should confirm serial-number requirements, software entitlement status, warranty expectations, and compatibility before approving substitutions. A visually similar part is not necessarily electrically, mechanically, or software compatible.
For regional deployments across Africa, logistics planning may also include customs documentation, import timelines, secure staging, and the availability of local hands for receiving and installation. These factors should be built into the schedule rather than treated as last-minute administrative tasks.
Test the Runbook Before the Change Window
A migration runbook should identify the task, owner, start condition, expected result, time budget, validation method, escalation contact, and rollback decision for every significant step. It must be usable by the engineer performing the work, not merely approved by management.
Test the runbook in a lab or staging environment whenever possible. Validate network configurations, routing adjacencies, VLAN propagation, firewall policies, storage connectivity, monitoring agents, backup jobs, and remote-management access. If the target environment uses new switch families or software releases, test the exact feature set required by production, including any legacy protocol support.
Conduct a formal readiness review before cutover. The review should confirm that backups are restorable, replication is current, support contacts are available, change approvals are complete, hardware is staged, and application owners understand their validation responsibilities. If a required input is unresolved, move the cutover rather than converting a known gap into an overnight incident.
Execute Cutover With Decision Points, Not Assumptions
During the change window, use one communications channel and one authoritative runbook. Record actual start and completion times, configuration changes, test results, and deviations. A designated change lead should control progression between steps so that parallel teams do not make conflicting changes.
Set explicit go, hold, and rollback checkpoints. For example, do not proceed from network cutover to application validation until management access, routing, DNS resolution, firewall flows, and monitoring are confirmed. If the primary service test fails, the team should already know whether to troubleshoot within the approved time budget or restore the previous environment.
Rollback must be technically credible. It requires preserved configurations, working source equipment, current data, known cable paths, and enough time to reverse the change. “Restore from backup” is not an adequate rollback plan for a service with a short outage tolerance.
Validate Operations After Migration
Successful boot-up is not final acceptance. Validate application transactions, user authentication, external connectivity, backup completion, alerting, performance baselines, and security logging. Compare interface errors, latency, packet loss, CPU utilization, memory utilization, and power draw against expected values.
Keep an intensified monitoring period after the migration. Issues such as incorrect MTU settings, asymmetric routing, missed firewall rules, optics faults, DNS cache behavior, and undersized uplinks may only appear under normal production load. Update diagrams, asset records, configuration backups, support contracts, and spare-part inventories as part of closure.
A controlled migration leaves the organization with more than equipment in a new location. It leaves a verified infrastructure record, a supportable hardware baseline, and a procurement plan for the components most likely to affect service continuity.

I am an enthusiastic tech blogger with 15 years of experience in the technology field. I am passionate about sharing valuable insights and helping people who are interested in technology gain useful and practical information. I am originally from Mumbai, India.



Leave a Reply